NLP-Cyber-Harm-Detection
NLP Cyber Harm Detection
Research code for nine-class scam detection, source-holdout evaluation and explanation experiments. The current reproducible classifier study fits word/character TF-IDF + LinearSVC models and publishes frozen split, validation-selection and final-test reports. Historical BERT, DistilBERT and generative-model checkpoints remain available for research; the newer classifier reports do not validate their original accuracy or generated explanations.
Project overview
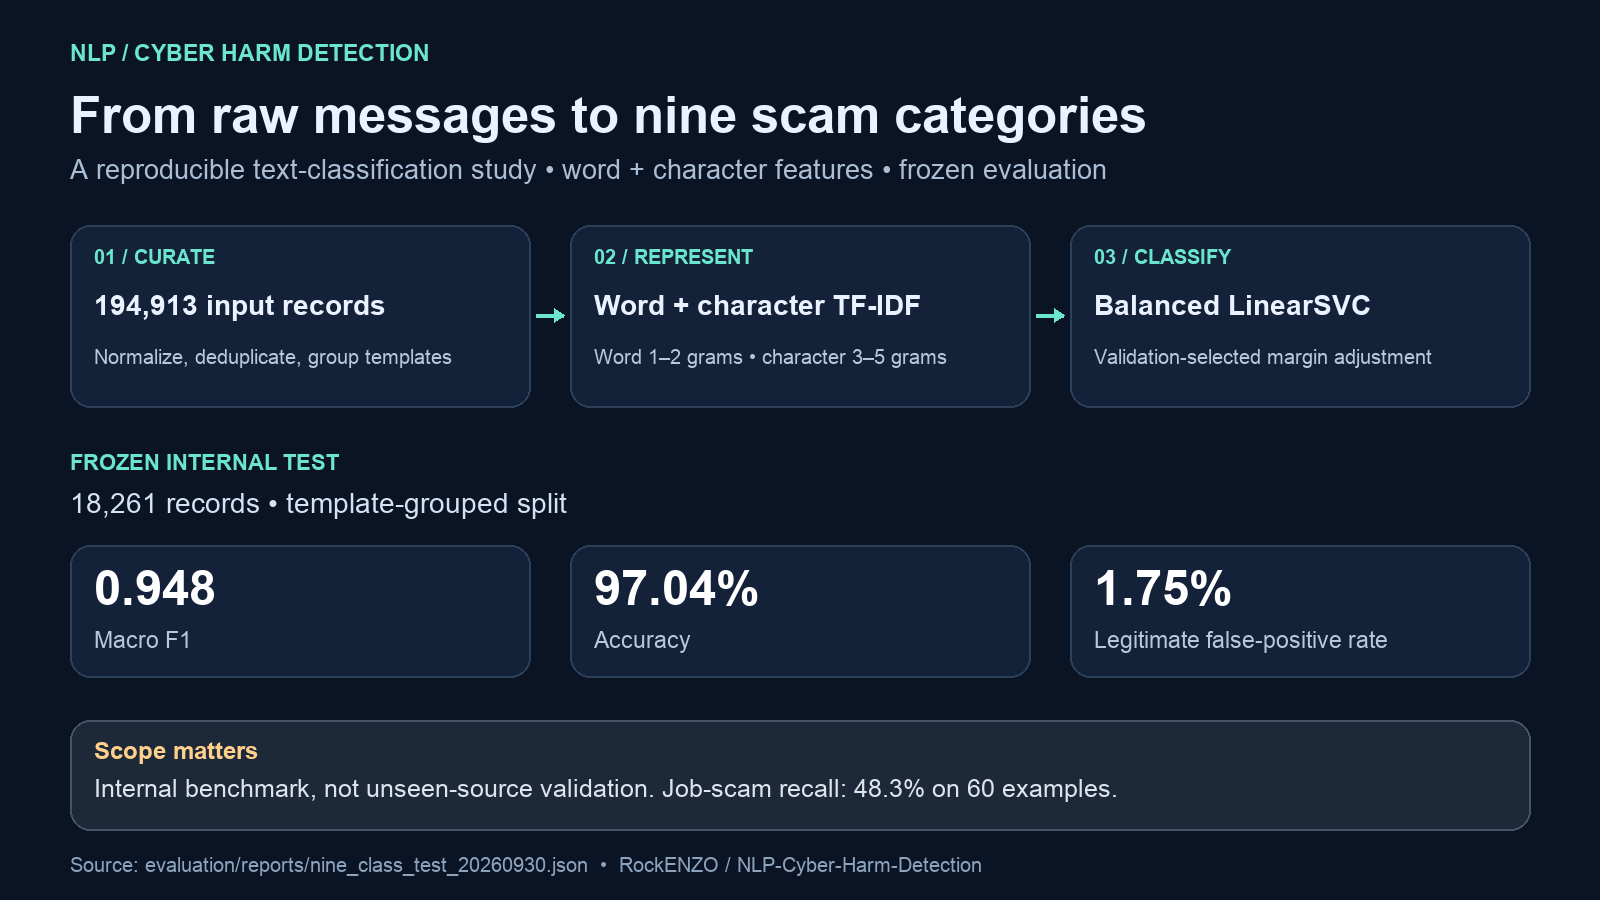
This visual summarizes the new nine-class TF-IDF + LinearSVC study, not the
historical neural or explanation models. Its numbers come directly from the
checked-in final test report.
Recreate the image with Pillow (python -m pip install Pillow), then run python docs/preview/render_preview.py. The unit suite also runs this renderer and checks the generated image’s dimensions and mode. It reads the report directly and uses the first Arial/DejaVu/Liberation font it finds, falling back to Pillow’s default; it is an overview rendered from the checked-in report, not a new measurement.
Current results and entry points
| Study | Published result | Interpretation |
|---|---|---|
| New nine-class word + character classifier | Macro F1 0.94768, accuracy 0.97043, legitimate FPR 0.01754 | 18,261-record template-grouped internal test; not unseen-source performance |
| Separate binary source-holdout baseline | Macro F1 0.7339, legitimate FPR 0.2455 | Entire DIFrauD source family held out; a different task and partition |
| Historical neural / explanation models | Original accuracy and explanation-quality claims unverified | No equivalent frozen checkpoint-specific held-out study |
For the current classifier, rebuild the reviewed corpus in a sibling data checkout using its documented recipe, then use Python 3.12:
GIT_LFS_SKIP_SMUDGE=1 git clone https://github.com/RockENZO/NLP-Cyber-Harm-Detection.git
cd NLP-Cyber-Harm-Detection
python -m venv .venv
source .venv/bin/activate
python -m pip install -r evaluation/requirements.txt
python evaluation/performance_study.py prepare
python evaluation/performance_study.py select
python evaluation/performance_study.py evaluate
python evaluation/predict_study.py --text 'Your appointment is confirmed for tomorrow.'
The default input is ../data/artifacts/verified/ (CSV plus provenance). Training generates local model artifacts; these are not bundled ready-to-download study checkpoints. Do not rerun the final evaluation to tune a model: the script refuses existing outputs and repeated final evaluation. See the complete protocol and limitations.
Historical BERT smoke demo
The BERT checkpoint and tokenizer are tracked with Git LFS. From the repository root:
GIT_LFS_SKIP_SMUDGE=1 git clone https://github.com/RockENZO/NLP-Cyber-Harm-Detection.git
cd NLP-Cyber-Harm-Detection
git lfs install
git lfs pull --include="models/bert_model/*"
python -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements.txt
python demos/quick_demo.py --text "Your appointment is confirmed for tomorrow"
The demo uses the checked-in models/bert_model and models/bert_tokenizer folders and prints a predicted label and model score. It is a smoke check, not a measurement of accuracy. The checkpoint is approximately 438 MB, so downloading it and running inference need adequate storage and memory. If Git LFS files are missing, git lfs pull --include="models/bert_model/*" is required before inference.
Evaluation
Follow the evaluation protocol before reporting a model score. It requires a source-disjoint held-out test set, frozen checkpoint and label mapping, exported predictions, and per-class metrics. The published source-holdout and nine-class reports below provide evidence for their newly fitted classical models. The original neural checkpoints lack recovered training IDs and an equivalent checkpoint-specific frozen held-out report, so their historical 94–96% accuracy and explanation-quality statements remain unverified here. Classification scores alone cannot validate generated explanations.
To score an exported prediction file with true_label,predicted_label columns:
python evaluation/evaluate_predictions.py held_out_predictions.csv --output evaluation.json
The scorer rejects malformed CSV rows and label mappings before writing a report.
Its default is the checked-in nine-class label universe; use --labels with an
ordered JSON array for another task. Absent classes remain in macro F1. Both the
prediction CSV and label-file byte snapshots are hashed in the report. See
the input and reporting contract.
The scorer aggregates prediction rows in one pass without retaining their CSV dictionaries; it still keeps exact byte/text snapshots for reproducible hashes. A synthetic allocation study and reproduction recipe reports the scoped memory result separately from model quality.
Repository map
demos/quick_demo.py: BERT inference smoke checkdemos/fraud_detection_demo.py: interactive BERT explorationtraining/: baseline and model training scripts and notebooksmodels/: saved checkpoints and tokenizers, many via Git LFSdocs/: architecture notes and evaluation protocolreasoning/: experimental explanation notebooks
See historical project notes for previous experiments and reported results. Those notes include older commands and performance claims that have not been independently verified against a frozen test set.
Reproducible source holdout baseline
The reviewed corpus has nine categories (eight fraud categories plus legitimate). evaluation/labels.json fixes their order for multiclass scoring, including zero-support categories. Unknown labels are rejected. Reports include legitimate false-positive rate and prediction-file SHA-256.
A new binary baseline was trained with the entire difraud_ source family excluded from training. This is a fresh TF-IDF + balanced Logistic Regression baseline, not a measurement of the bundled neural checkpoints.
| Metric | Reviewed run |
|---|---|
| Training rows | 158,909 |
| Held-out source rows | 36,004 |
| Accuracy | 0.7773 |
| Macro F1 (binary) | 0.7339 |
| Legitimate false-positive rate | 0.2455 |
See full report for per-source metrics, parameters, input/provenance hashes, split/prediction hashes and runtime versions. These results show substantial false-positive and cross-source generalization problems; they do not support a production-readiness claim.
# In the data repository, use the reviewed build from its README first.
# Then in this repository (Python 3.12):
pip install -r evaluation/requirements.txt
python evaluation/source_baseline.py \
  --data ../data/artifacts/verified/final_fraud_detection_dataset.csv \
  --provenance ../data/artifacts/verified/provenance.jsonl \
  --output-dir runs/source-baseline
python evaluation/evaluate_predictions.py runs/source-baseline/predictions.csv \
  --labels evaluation/binary_labels.json --output runs/source-baseline/scored.json
The partition verifies row order, content hashes, unique texts and provenance before fitting. No vocabulary is fitted on test texts. It writes exact train/test sample IDs in split_manifest.json; predictions contain sample IDs and source identifiers without message content. Test source identity is excluded from features. Source grouping does not prove template/semantic independence, and inherited spam/fraud labels require further adjudication.
For existing BERT/T5/BART/LLM checkpoints, their original training IDs and untouched held-out data must be recovered before publishing accuracy. The combined corpus may already have been used in training, so scoring these checkpoints on a newly chosen subset is not a valid held-out evaluation. Explanation faithfulness also requires a separate reviewed annotation protocol; this binary classifier report makes no explanation-quality claim.
Improved nine-class classifier study
This experiment trains new classifiers from scratch and compares them on the same frozen template-grouped split. It addresses the complete nine-category task; it is a separate in-corpus study and must not be compared numerically to the earlier unseen-source binary benchmark as if they used the same test set.
Dataset: 194,913 input records; 11,809 normalized duplicates and 99 records in conflicting-label template groups were excluded before fitting. Retained split: 146,512 training, 18,232 validation, 18,261 test records. URL/email/number variants are grouped after Unicode normalization. Official DIFrauD test/validation boundaries take priority within groups; other groups use a deterministic hash split. Each retained template contributes one representative. All nine labels are represented in every split.
| Frozen internal test metric | Word SVM baseline | Selected word + character SVM |
|---|---|---|
| Nine-class macro F1 | 0.93789 | 0.94768 |
| Nine-class accuracy | 0.96293 | 0.97043 |
| Legitimate false-positive rate | 0.03366 | 0.01754 |
| Binary fraud recall | 0.96177 | 0.95748 |
The selected model uses word 1–2 grams and character 3–5 grams, a balanced LinearSVC and a +0.25 legitimate-class decision-margin offset. Model/offset selection uses validation only: first require legitimate FPR <=3% and fraud recall >=80%, then maximize nine-class macro F1. The final test is evaluated once after selection. This reduces false positives by approximately 48% relative to the matched baseline with a small recall tradeoff.
Split protocol, complete validation selection and per-class/per-source final results include hashes and support counts. Exact split IDs, predictions and locally trained models are generated under runs/nine-class-study/.
# Rebuild the reviewed data corpus first, following the earlier section.
pip install -r evaluation/requirements.txt
python evaluation/performance_study.py prepare
python evaluation/performance_study.py select
python evaluation/performance_study.py evaluate
python evaluation/predict_study.py --text 'Your appointment is confirmed for tomorrow.'
The script refuses existing study/model output directories or a second final test evaluation. The inference CLI checks the model hash against the frozen selection. Only load trusted locally generated joblib artifacts; joblib is not a safe format for untrusted downloaded files. Decision margins are not calibrated probabilities.
Interpretation and resume wording
An accurate statement is: “Built a reproducible nine-class text classifier; on an 18,261-record template-grouped internal test, achieved macro F1 0.948 and reduced legitimate-message false positives from 3.37% to 1.75% versus a matched baseline.”
This describes a benchmark result, not universal scam detection. Some dialogue categories include synthetic content and show near-perfect separation; aggregate macro F1 should be read with the per-class results. On the 60 job-scam test examples, recall is 0.4833 and F1 0.6237. Unknown sources, semantic near duplicates, label adjudication, dataset shift and explanation faithfulness remain separate research questions. The new study does not validate any existing BERT/T5/BART/LLM checkpoint or its explanations. No deployment-readiness claim is made.
Source-baseline input provenance
The binary source-family baseline reads the data CSV and provenance JSONL into byte snapshots before training. Its input hashes identify those exact parsed snapshots, even if the original paths change during fitting. This uses memory proportional to both input files in addition to parsed training records. It does not make two separately stored files an atomic dataset version; existing row-order and text-identity checks still validate their pairing. No model has been retrained and existing reported metrics are unchanged by this engineering fix.
README reference checks
The README references workflow checks local Markdown destinations and supported
script/requirements paths on pushes and pull requests. It runs on all source
changes because deleting a documented file can break the README without changing
the document itself. The checker is pinned to the reviewed Readme Reality
v0.1.1 commit and uses read-only source access; it does not install this project’s
dependencies, download LFS weights, execute commands or evaluate a model.
Read the job’s annotations and summary, including skipped coverage. Complex setup blocks, external URLs, generated artifacts and unsupported commands remain outside these static checks. A green result does not establish that training or inference works, that weights have been downloaded, or that reported metrics are valid.